Private AI Assistant with RAG
Dedicated assistant tuned to your business with retrieval-augmented responses grounded in your documents.
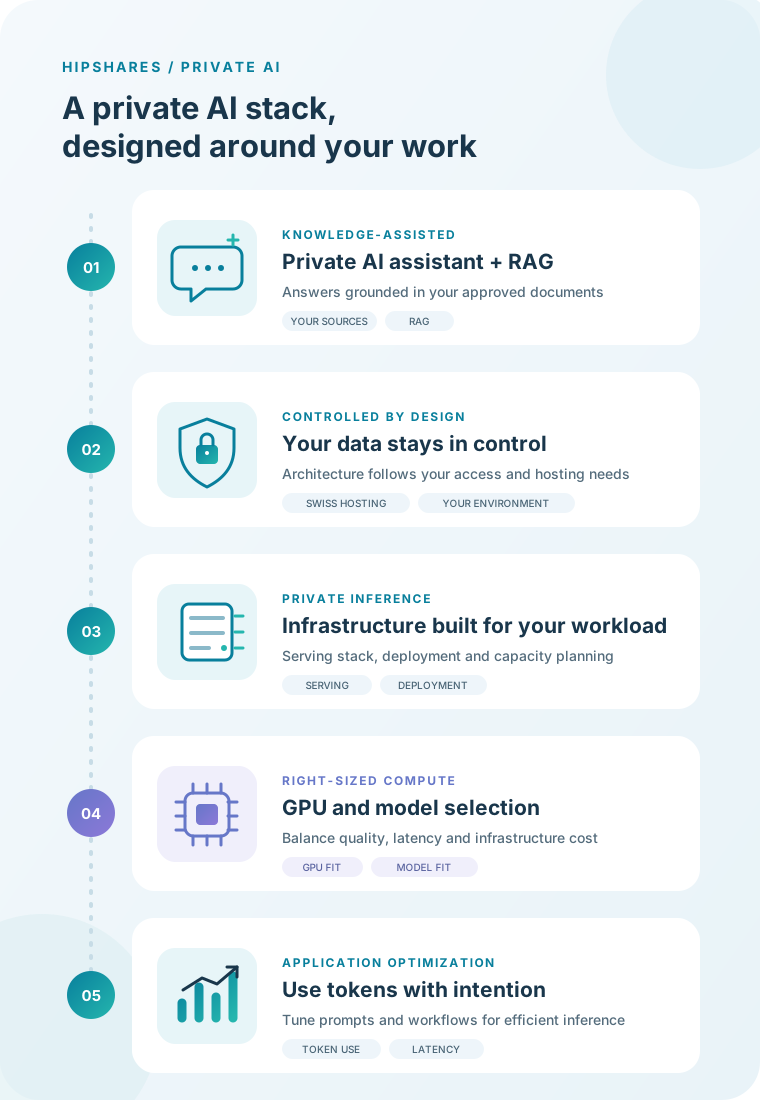
We provide private AI consulting, inference infrastructure setup, and application optimization, from model and GPU selection to deployment and efficient token use.
Dedicated assistant tuned to your business with retrieval-augmented responses grounded in your documents.
Deployment options can include infrastructure in Switzerland or a server in your own environment. Data access, retention, and model-provider terms depend on the selected architecture and are defined during project design.
Practical AI capabilities built around the task and deployed on infrastructure sized to your requirements.
We plan and set up infrastructure for private AI inference, including the serving stack and deployment architecture sized to your workload.
We advise on fit-for-purpose GPU options and optimize AI applications to reduce unnecessary token use while balancing answer quality, latency, and inference cost.
Practical ways teams can use an assistant that retrieves relevant information from approved internal sources.
Ask questions in natural language and find relevant information in your approved knowledge sources.
Speed up onboarding with concise answers pulled from policies, playbooks, and guides.
Assist support teams with accurate responses grounded in product and troubleshooting docs.
Surface the right collateral, messaging, and case studies for prospects instantly.
Help teams follow internal rules with sourced, auditable answers from policy libraries.
Search and summarize contracts or procedures with traceable references.
Protect sensitive information while getting reliable, context-aware answers that fit your workflows.
Deployment and access controls aligned with agreed data requirements
Answers can include references to source material
Built around your teams workflows and tone
Lightweight deployment without heavy hardware
Easy to extend with new sources and automations
